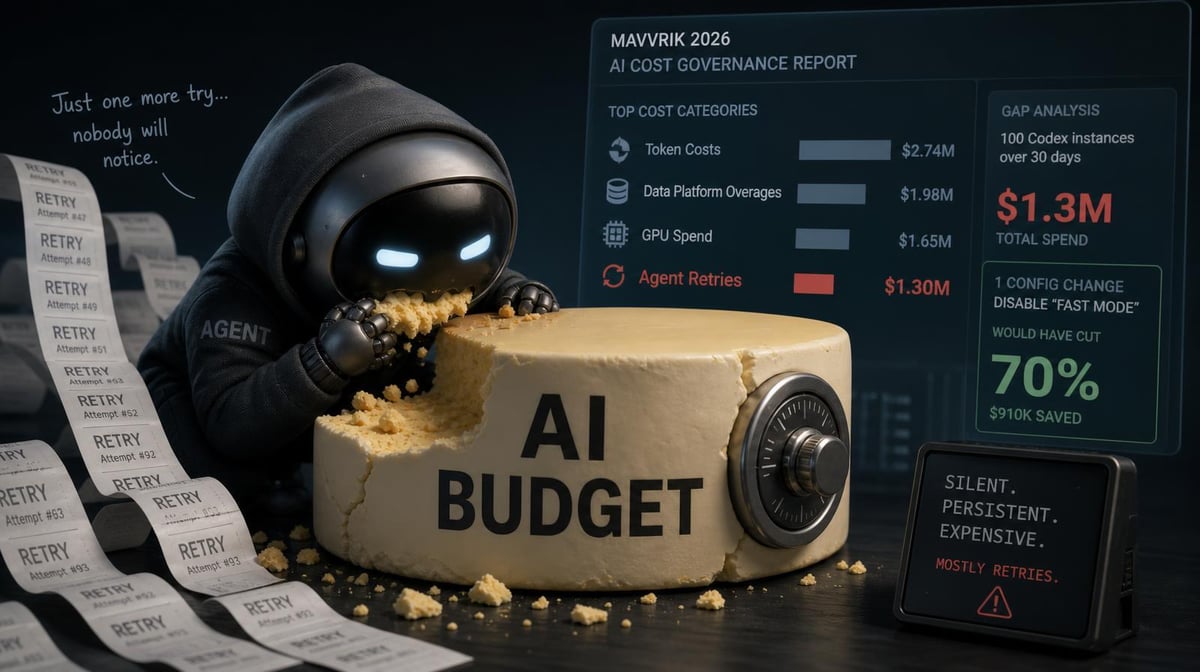

An AI agent can fail in a very expensive way: it can keep trying.
In May 2026, an OpenClaw bug report documented two idle-timeout incidents in which a single failure triggered 761 and 1,384 model calls within 60 seconds. The reporter estimated each event cost $$30 before an external monitor caught it. OpenClaw merged a circuit-breaker fix the next day.
That’s the retry-cost problem in one minute: a normal failure becomes a spending event because nothing stops the system from retrying.
Key Takeaways
- OpenClaw responded to the runaway retry bug by adding a circuit breaker that caps consecutive idle-timeout model calls at five by default, showing how bounded retries can turn an open-ended cost risk into a controlled failure.
- It’s hard to tell the difference between retry-loop costs and productive agent spend in aggregate reporting. Session-level monitoring is what reveals repeated calls, rising spend, and little or no progress within a single run.
- A June 2026 preprint cataloged 63 LLM-agent budget-overrun incidents across 21 orchestration frameworks and identified retry loops as one production failure class. The broader lesson isn’t that every retry is waste. It’s that unbounded retries need explicit cost controls.
How Retry Loops Turn Failures Into Cost Spikes
Retries are normal in software. A temporary timeout or failed tool call may succeed on the next attempt. The problem starts when the system keeps retrying without a clear limit or way to stop and flag the failure.
The OpenClaw incident shows the problem clearly. A model call hit an idle timeout, the upstream layer retried it, and the same condition repeated in a tight loop. The bug reporter said each retry processed the full session context, making hundreds or thousands of paid calls before an outside monitor intervened.
That doesn’t mean every agent re-sends an ever-growing full context on every retry. Cost behavior depends on the architecture, provider, caching, and context strategy. But every paid model call consumes budget, and long agent runs can make repeated calls a lot more expensive when they carry large contexts.
The risk isn’t limited to one system. In a user-reported Claude Code issue from March 2026, a session with a heavily occupied context window reportedly continued sending repeated requests for hours after a compaction attempt, resulting in more than $500 in unexpected usage. The process was different from the OpenClaw timeout bug, but the governance failure is similar: repeated model calls continued to consume tokens without an effective cutoff.
Why Monthly Spend Reporting Is Not Enough
An invoice can tell you that spend increased. It can’t tell you whether the increase came from productive agent work, heavy but intentional use, or one malfunctioning run.
Retry problems show up as patterns in agent activity: repeated calls or attempts from the same run over a short period, rising token or cost consumption without corresponding progress, repeated timeout or tool-error signatures, or a session that continues far longer than its task normally requires.
You need more detail than a monthly total to tell productive agent spend from a runaway retry loop. Larridin’s Token Spend & Insights connects AI spend to teams, agents, projects, workflows, and models. Larridin’s developer productivity measurement also treats session cost and retry spend as distinct inputs, so leaders can separate productive spend from activity that is being consumed by failed attempts.
Four Controls That Limit Retry-Loop Cost Events
1. Set Retry Limits
Every production agent should have a defined retry policy rather than an implicit “keep trying” behavior. That can include a maximum number of attempts, backoff between retries, and a circuit breaker that stops paid calls when the same failure repeats.
OpenClaw’s fix is a good example. It added a circuit breaker with a default cap of five consecutive idle timeouts. After the cap is reached, later attempts are refused without making another paid model call. Successful model output resets the counter, so the control does not treat a slow-but-working run the same as a stuck one.
2. Put a Budget Around the Run
Retry limits constrain one failure pattern. A per-run token or cost budget protects against a wider set of runaway behaviors, including loops that do not present as identical retries.
The June 2026 token-budget preprint focuses on this problem directly: agent spending controls should be enforceable within the execution path rather than depending on someone noticing the bill afterward. The exact cap should reflect the workload. A complex multi-file coding task needs a different budget from a short classification or documentation task.
3. Monitor Agent Runs for Cost Anomalies
Hard limits prevent the worst-case scenario. Monitoring helps explain what’s happening before the limit is reached.
Track cost, token use, retries, tool errors, duration, and outcome at the run or session level. A run that repeatedly consumes tokens without producing accepted output is a different operating signal from a costly run that completes valuable work. Larridin’s Token Spend & Insights attributes spend across agents, teams, workflows, and outcomes, while its developer productivity measurement includes session cost and retry spend as cost-effectiveness signals.
4. Give Every Agent an Owner
A cost control without an accountable person still leaves a governance gap. Every production agent should have an owner, an escalation path, and thresholds that determine when someone needs to investigate.
We’ve found 47 orphaned agents on average in our enterprise scans: active agents with no accountable owner attached. For retry risk, ownership matters because a runaway run needs someone to decide whether to stop it, change the workflow, or fix the underlying failure.
Frequently Asked Questions
How do we know if retry loops are driving AI cost in our environment?
Look for repeated attempts within the same run, especially when they cluster around the same error or timeout and produce little or no progress. Pair that trace data with session-level cost, token consumption, run duration, and task outcome. High cost alone does not prove a retry loop; the repeated failure pattern does.
What can trigger an agent retry loop?
The trigger depends on the system. The OpenClaw incident started with an idle timeout. The Claude Code user report involved a context-exhaustion scenario after compaction. Other loops can begin with failed tool calls, unavailable dependencies, or success and failure conditions that do not tell the agent when to stop. The common governance problem is allowing the failure to generate paid work indefinitely.
Are retry limits enough to control runaway agent costs?
No. Retry limits address repeated failures, but agents can generate excessive spend through long runs, repeated tool use, oversized context, parallel sub-agents, or expensive model routing. Use retry controls alongside per-run budgets, rate limits, cost alerts, context management, and agent-level attribution.
Can strict retry controls stop legitimate agent work?
They can if they’re set without regard to the workload. That’s why retry controls should distinguish repeated failure from legitimate progress. OpenClaw’s circuit breaker, for example, resets after a successful chunk arrives. Budget limits should likewise vary by task type rather than forcing every run into the same ceiling.
See Retry Spend Before It Becomes Runaway Spend
Larridin connects AI spend to agents, teams, workflows, and outcomes, helping leaders distinguish productive agent activity from retries, abandoned work, and other spend that is not producing durable value.
Book a discovery call to see where agent-driven AI spend is going before the invoice is the first warning.