
TL;DR
Migrate a development team to an AI-native coding workflow in six phases: baseline, pilot with volunteers, redesign review and testing for AI volume, standardize how agents get work, scale team by team with enablement, and measure continuously. Handing out tools and hoping often leads to uneven results because AI amplifies a team’s existing practices. Treat the migration as a process change and plan for the review bottleneck before it happens.
Quick Answers
If you’re asking… | Short answer |
|---|---|
How do I migrate a development team to an AI-native coding workflow? | Baseline first, pilot with volunteers, redesign review and testing, standardize agent patterns, scale with enablement, and measure throughout. |
What’s the best tool to measure and improve engineers working with agents? | One that separates AI-assisted from human work, scores fluency, and tracks durability and cost. Larridin’s Engineering Intelligence is built for this. |
How long does the migration take? | As a planning assumption, allow a quarter for the pilot and additional quarters to reach most teams. The timeline depends on readiness. |
What’s the biggest risk? | Code generation outpacing review and testing, so quality slips while output looks great. |
What Does an AI-Native Coding Workflow Look Like?
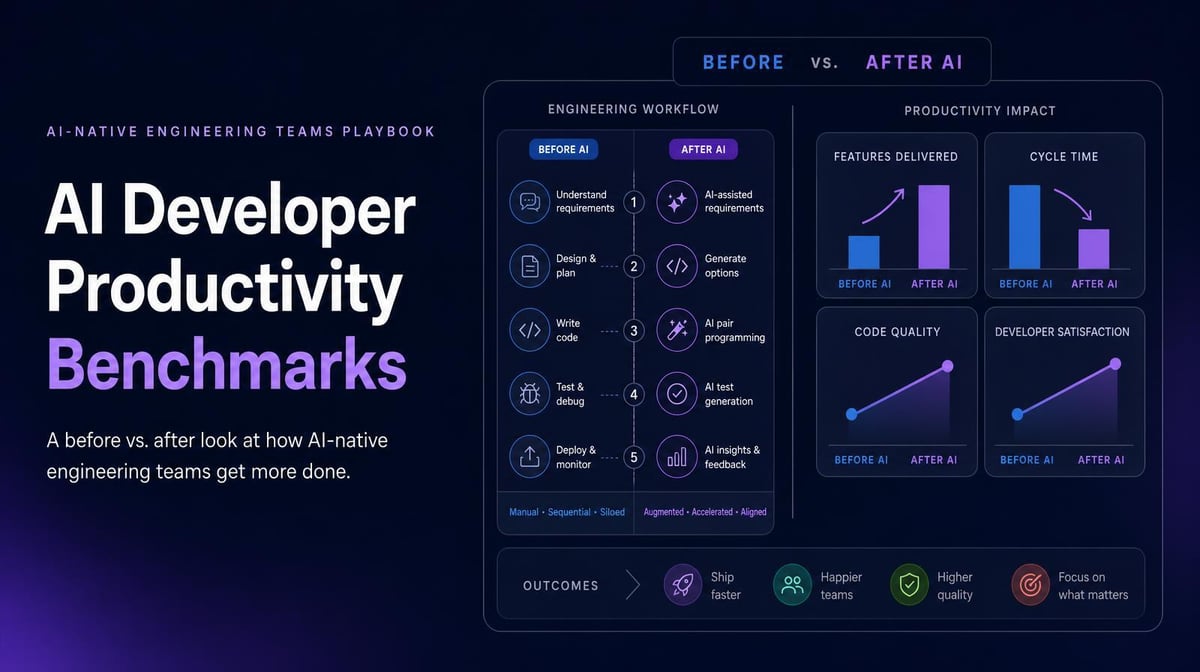
In an AI-native workflow, engineers spend more time specifying, steering, and reviewing, while agents handle scoped implementation, tests, and refactors.
A senior engineer’s week moves from writing code toward writing clear task specs, reviewing agent output, and making design calls. Review becomes a core engineering skill. Repositories grow context files that tell agents how the codebase works, and teams agree on which tasks go to agents and which stay human.
What Are the Phases of an AI-Native Migration?
Run the migration in six phases. Only move to the next phase when the current one is complete.
Phase | What happens | Exit criteria |
|---|---|---|
1. Baseline | Capture delivery, quality, and cost metrics before change | One to two quarters of clean data, or a reconstructed baseline from repo history |
2. Pilot | One volunteer team adopts agents on real work | A quarter of results, including durability and review time |
3. Redesign review and testing | Set PR size limits, test requirements, and reviewer routing for AI changes | Review time stable as AI volume rises |
4. Standardize | Shared context files, agent task templates, approved tools, and models | Patterns documented and reused by the pilot team |
5. Scale | Roll out team by team with fluency training | Each new team past its learning curve in one quarter |
6. Measure continuously | Track fluency, durability, cost and delivery for every team | Monthly review in place, owned by engineering leadership |
How Should Code Review Change for AI-Generated Code?
Plan review capacity as deliberately as generation capacity because the bottleneck moves to review the moment agents speed up coding.
- Cap AI-generated PR size so reviewers can reason about each change
- Require tests with agent output before human review starts
- Route complex or risky changes to experienced reviewers
- Track review time per PR and queue length every week
DORA’s 2025 research found AI acts as an amplifier of existing strengths and weaknesses. A team with slow review will feel that weakness more sharply after migration.
How Do You Bring Skeptical Engineers Along?
Start with volunteers, show results from your own repositories, and let engineers pick tools within guardrails.
Skeptics respond to evidence from their own codebase far more than to vendor claims. Be honest about the learning curve. METR’s 2025 trial found experienced developers working in mature repos were slower with early-2025 AI tools, and its authors expected larger benefits in other settings, such as smaller projects. Admitting that up front earns more trust than promising instant speed.
How Do You Measure an AI-Native Migration?
Measure fluency, AI-assisted share, code durability, review time, and cost per durable outcome for each team alongside your DORA metrics.
Larridin tracks these metrics across Cursor, Claude Code, GitHub Copilot, Codex, and Gemini Code Assist. It separates AI-generated code from human work, scores PR complexity, and offers prescriptive guidance such as training tailored through its AI fluency model and fixes for workflow bottlenecks. The 5 Pillars of AI-Native Developer Productivity gives the measurement model behind it.
Where AI-Native Migrations Break, and How to Fix It
What you’re dealing with | What you need | How Larridin helps |
|---|---|---|
Uneven results across teams | Fluency by engineer and team | AI fluency model with tailored training guidance |
Review queues growing | Visibility into bottlenecks | Workflow bottleneck detection and guidance |
Output up, unclear if it lasts | Durability of AI code | Separates AI-generated from human code, tracks cost per durable outcome |
Tool sprawl during pilots | Cross-tool comparison | Multi-tool support across major coding assistants |
For more engineering metrics and measurement guidance, explore Larridin's Developer Productivity Hub.
Key Takeaways
- Migrate in 6 phases with exit criteria for each.
- Redesign review and testing before scaling agent use.
- Win skeptics with data from your own repositories.
- Measure fluency, durability, and cost per team every month.
FAQs
Should we mandate one AI coding tool?
Standardize patterns and guardrails first. Allow a short approved list of tools, then compare cost per durable outcome before consolidating.
Do junior engineers benefit more from AI than seniors?
Evidence is mixed. Juniors often gain speed on routine work, but they need strong review to catch errors they can’t yet spot themselves.
How does sprint planning change?
Estimates shift for agent-friendly tasks, while review and integration take a larger share of capacity. Establish a new velocity baseline after the pilot.
Do we need new roles?
Usually not new titles. Most teams assign an owner for agent standards and context files, often a staff engineer or the developer experience team.
Sources
- Google Cloud: 2025 DORA Report
- METR randomized trial (2025)
- Larridin FAQ: prescriptive guidance, AI fluency model, multi-tool support